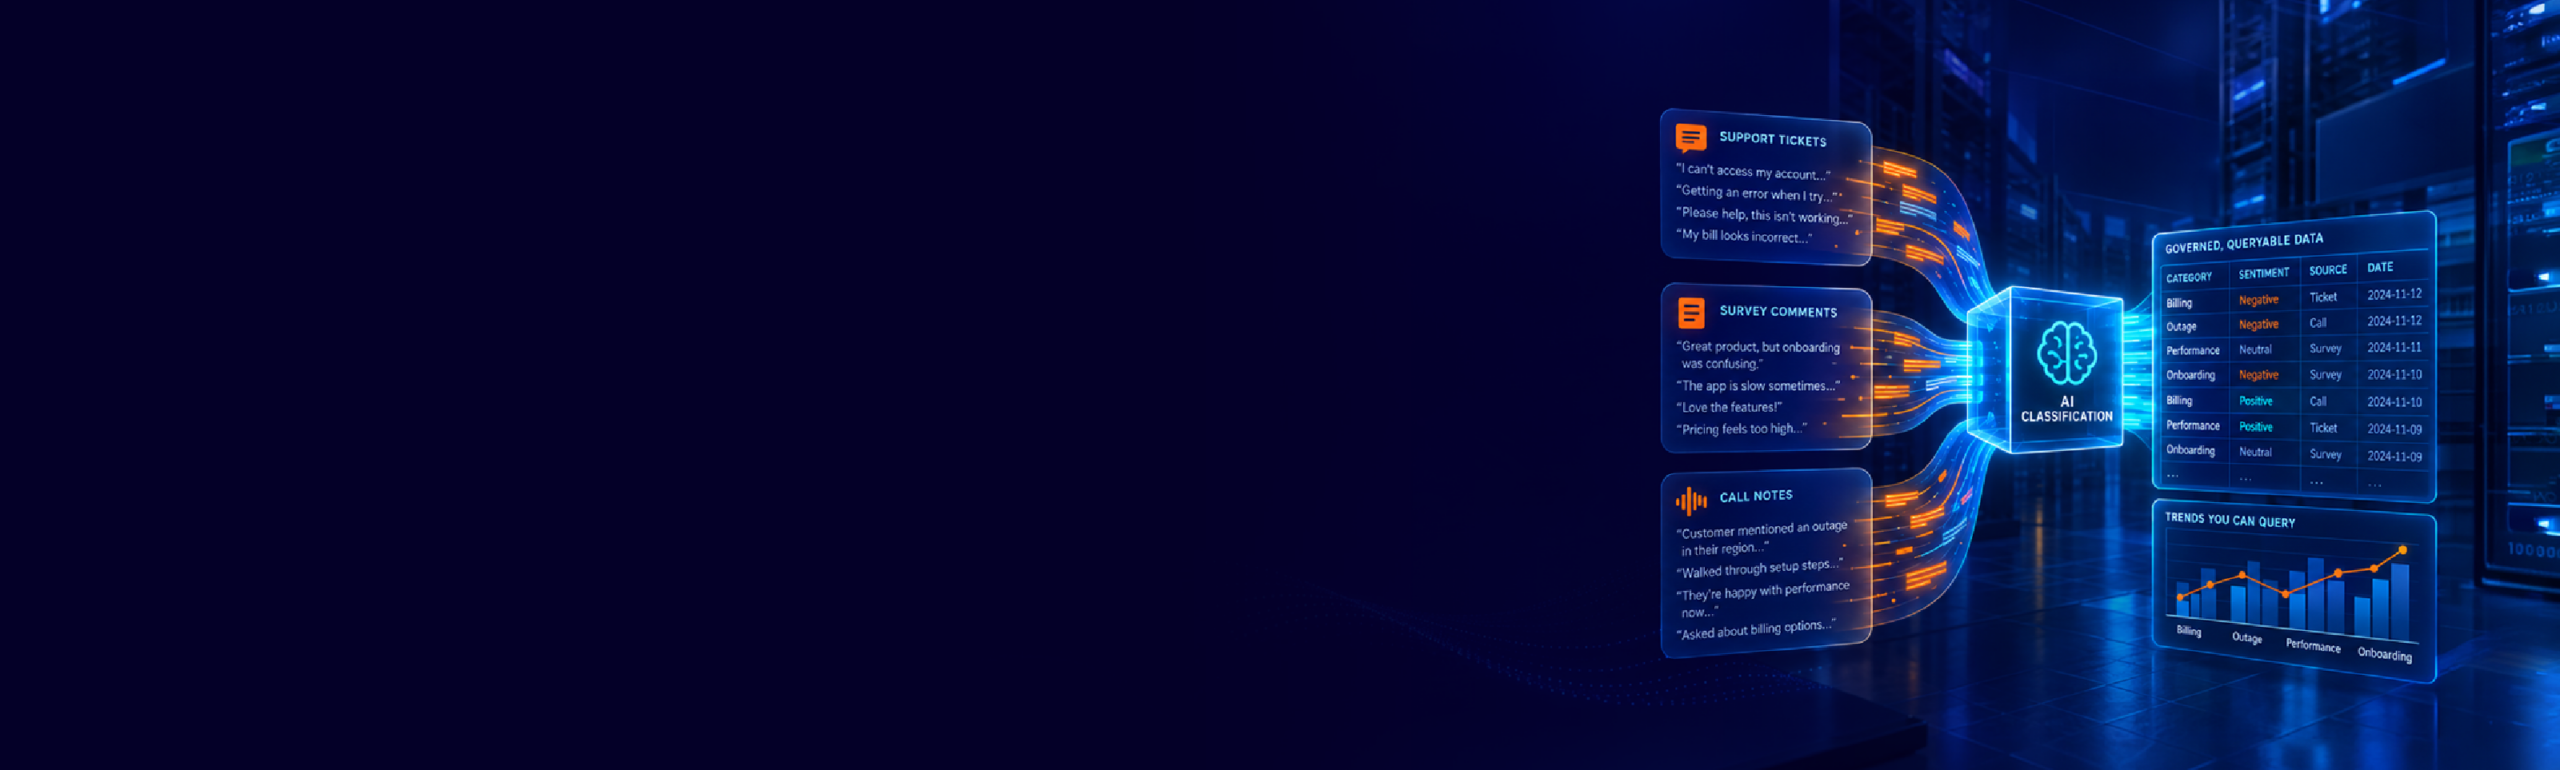
Your business is probably sitting on thousands of customer comments, support tickets, survey responses, and call notes. Each one contains useful information. The problem is that none of it fits neatly into a dashboard.
Imagine your VP of Customer Experience asking a straightforward question during a Monday meeting: “What are customers actually complaining about this quarter?”
You have 40,000 support tickets, 12,000 survey comments, and six months of call notes. Somewhere in that text is the answer. But without a practical way to analyze it, someone ends up reading a sample of 200 responses and reporting back the following week.
That may give you a general impression. It does not give you the full picture.
What Topic Modeling and AI Classification Actually Do
Topic modeling looks across a large collection of text and identifies themes that appear repeatedly. Those themes do not need to be defined in advance. The technology finds patterns based on the language people are already using.
AI classification takes the process one step further by applying structured labels to individual records. Instead of producing another summary for someone to read, it creates a column that analysts can filter, group, join, and track over time using SQL.
That difference is important. It turns thousands of disconnected comments into data the business can measure and use.
It also addresses a growing problem for organizations investing in AI. As Gartner noted in its report, “Lack of AI-Ready Data Puts AI Projects at Risk”, many AI initiatives are being held back by data that is not ready for practical use.
Free text makes up a significant portion of the data many companies collect, yet it is often the least accessible. Preparing that information for analysis doesn’t happen before the AI work begins. In many cases, it is the AI work.
The Business Challenges It Solves
Understand the full voice of the customer
Reading 200 responses out of 12,000 gives you a snapshot. Classifying all 12,000 gives you something much more useful: a measurable view of what customers are saying across the entire dataset.
You can see which issues appear most often, how they change month to month, and whether a complaint is isolated or part of a broader pattern. Customer feedback becomes a metric the business can track, not a collection of anecdotes.
Route support tickets more effectively
Support tickets usually arrive as paragraphs, not clean categories. Classification can label each ticket as it enters the system and help route it to the team most likely to resolve it.
The goal is not simply to create a better dashboard. It is to reduce how often a ticket gets reassigned and shorten the time it takes for the customer to receive a useful response.
Catch emerging problems earlier
Customers often notice a defect, outage, or billing issue before it becomes visible in an operational report.
Once feedback is classified, teams can monitor how quickly individual themes are growing. If mentions of a particular issue suddenly triple in a week, the business can investigate before the problem becomes widespread.
Identify important combinations
Multi-label classification is especially helpful when a single comment touches several topics.
For example, you might want to identify customers who mention both pricing and a competitor. A compliance team may need to review messages that reference a regulated topic alongside a specific product or service.
With structured labels, those questions become repeatable queries instead of one-time keyword searches stored in someone’s workbook.
How Snowflake Supports the Process
Three Snowflake capabilities make this pattern possible.
AI_CLASSIFY performs zero-shot classification directly in SQL. You provide a list of categories and descriptions, and Snowflake applies the appropriate labels to each record. It can return a single label or multiple labels, depending on the use case. You don’t need a separate training dataset or a model to host.
AI_COMPLETE gives teams access to frontier models, including Anthropic’s Claude, from within a query. One useful application is turning a machine-generated group of keywords into a category name that makes sense to the business.
Snowpark supports the Python-based work that topic discovery may require while keeping that processing close to the data.
Together, these capabilities let teams analyze text within Snowflake instead of building a separate environment around it. There are no external API keys to manage, no exports to coordinate, and no additional batching or retry process to maintain. The resulting labels remain alongside the original data and can follow the same role-based access controls.
As a Snowflake Elite Partner, 7Rivers implements this pattern within a customer’s existing Snowflake account rather than adding a parallel platform that the customer then has to manage.
In practice, you can handle the classification with a single SQL statement. Each category includes a short description to give the model enough context to distinguish similar issues. For example, that description can help it separate a product that is running slowly from one that is completely unavailable.
CREATE OR REPLACE TABLE support_tickets_classified AS
SELECT
ticket_id,
created_at,
ticket_text,
AI_CLASSIFY(
ticket_text,
[
{'label': 'Billing',         'description': 'Invoices, charges, refunds, or anything about what the customer was billed.'},
{'label': 'Outage',          'description': 'The product or a specific feature was unavailable, down, or unreachable.'},
{'label': 'Performance',     'description': 'The product worked, but was slow, laggy, or timed out.'},
{'label': 'Feature Request', 'description': 'A request for functionality that does not exist yet.'},
{'label': 'Onboarding',      'description': 'Setup, configuration, migration, or getting started with the product.'}
],
{'output_mode': 'multi'}
):labels AS themes
FROM support_tickets;
Multi-label mode returns an array of relevant themes for each ticket. If none of the categories fit, it can return an empty array instead of forcing the record into an inaccurate category.
Once those themes are stored in a column, the question from the Monday meeting becomes a standard SQL query. LATERAL FLATTEN creates one row for each theme, allowing analysts to aggregate the results as they would with any other structured field.
-- Theme volume by month: the metric that replaces "we read 200 of them"
SELECT
DATE_TRUNC('month', tickets.created_at) AS month,
themes.value::STRING AS theme,
COUNT(*) AS ticket_count
FROM support_tickets_classified AS tickets,
LATERAL FLATTEN(input => tickets.themes) AS themes
GROUP BY ALL
ORDER BY month, ticket_count DESC;
Instead of asking someone to read a sample and summarize what stood out, the VP can see defensible counts across the full set of customer feedback.
For a deeper technical walkthrough covering embeddings, BERTopic, and Snowpark implementations, see Love at First (Snow)sight.
Where This Fits in the 7Rivers Data Native® Model
Unstructured text analytics fits within the Business Insights stage of the 7Rivers Data Native® model. It can also create a fairly direct path from Insights to Actions.
Many organizations have already completed much of the foundational work. Their migration is finished, the warehouse is governed, and teams trust the dashboards they use every day. But the text fields in those same systems remain largely untouched.
The business can report on transactions, totals, and percentages, yet still struggle to answer basic questions about what customers, employees, or partners are actually saying.
Closing that gap is often more manageable than teams expect. Start with one text collection, build a focused category list, and have subject-matter experts review the results. Once the labels are reliable, the same column can support reporting, ticket routing, alerts, or a GenAI application.
Where This Goes Next
You do not need to classify every piece of text your organization has collected.
Start with the column people already spend time reading manually. It might be support ticket descriptions, survey comments, sales call notes, warranty claims, or incident reports.
Then ask three questions:
- What decisions are people trying to make from this text?
- Which categories would make those decisions easier?
- Who understands the subject well enough to validate the labels?
That first use case can show where classification is genuinely useful, where the category definitions need work, and what level of accuracy the business requires before automating anything downstream.
The opportunity is straightforward: take information your company already collects and make it available for the same analysis, governance, and action as the rest of your data.
Ready to turn your text into columns? Book an unstructured data readiness assessment with the 7Rivers data science team. We will help identify your highest-value text source, develop a practical category list with your subject-matter experts, and scope the classification pipeline within your existing Snowflake account.
If your data foundation still needs work, begin with a Data Native® Strategy & Roadmap workshop.